
Prompt chaining vs chain of thought: inside or between calls
Chain of thought happens inside one model call. Prompt chaining, between several. Which to use, when to combine them, and the same example with both.
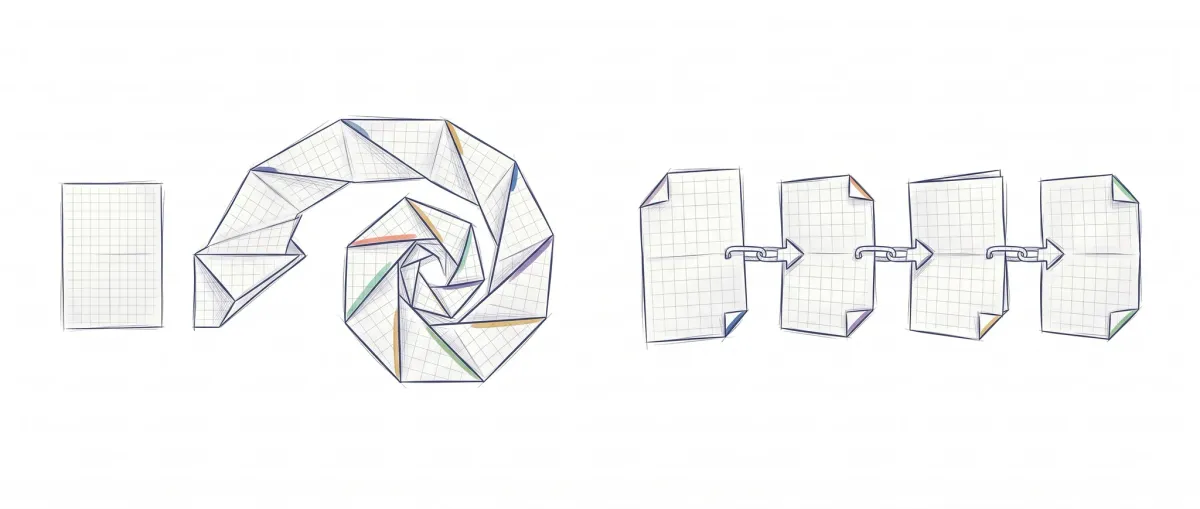
Both names have the word “chain” in them, which is why we tend to use them as synonyms, but they solve different problems and live on different layers of the system. Chain of thought happens inside a single call to the model. Prompt chaining happens between several calls. That sentence clears up most of the confusion, and the rest of this article is what follows from it.
Think of it as a colleague at the next desk. Chain of thought is asking them to talk through their reasoning out loud while they solve the whole problem in one sitting: at the end you get their answer and their explanation, all together. Prompt chaining is asking for one thing, looking at what they hand back, and only then asking for the next. In the first case you cannot interrupt halfway. In the second, you can.
To follow this you only need to know what an LLM is (the model you send text to and get text back from) and to have written a prompt at some point. Nothing else.
Prompt chaining vs chain of thought: the difference in one table
| Chain of thought | Prompt chaining | |
|---|---|---|
| What it is | A prompting technique: you ask the model to reason before giving you the answer | An architecture technique: you split the task and chain calls |
| Where it happens | Inside one call | Between calls |
| Number of calls | One | Two or more |
| Where the intermediate state lives | In that call’s context, that is, in the model’s working memory | In variables in your code |
| What you can inspect | The final text, and the reasoning only if the model hands it back | The output of each step, before passing it to the next |
| What you can validate | Nothing halfway through | Each step, with an ordinary if |
| If something goes wrong | You repeat the whole call | You retry only the step that failed |
| Cost and latency | One prompt, one wait | Several prompts and several waits, each one shorter |
Two words from the table, in case you only half know them. The intermediate state is the half-finished result: in the example below, a ticket’s category before the reply has been written. Latency is how long a call to the model takes to come back, counted from the moment you send it: two short calls add up their two waits, even though each one is faster than a long one.
Look at the state row, because it is the one that really drives things. Everything else follows from it: if the intermediate result is inside the model, your code cannot see it, check it or correct it. If it is in a variable in your code, you can do with it whatever you would do with any other data.
The term chain of thought comes from a 2022 paper by Jason Wei and his team, where they showed that asking the model for the intermediate steps rather than just the result greatly improved its performance on reasoning problems [1]. Prompt chaining is a different family: Anthropic defines it as decomposing a task into a sequence of steps where each call processes the output of the previous one [2].
The same example with both techniques
Let’s take a concrete task: a support ticket arrives written in free text and you want two things, to classify it and to draft a reply.
With chain of thought: one call
Here you ask the model to think before answering and hand you everything together. I am using Anthropic’s official TypeScript SDK.
import Anthropic from "@anthropic-ai/sdk";

// Create the client (it uses the ANTHROPIC_API_KEY environment variable)
const client = new Anthropic();

// The ticket text. I'm writing it by hand here; in your case it would come
// from a form, an email, or the database
const incidencia = "I haven't been able to log in for three days and you've charged me for the month.";

// The API returns a LIST of blocks (text, images, other types):
// this function keeps only the text ones and joins them into a string
function texto(res: Anthropic.Message): string {
  return res.content.map((b) => (b.type === "text" ? b.text : "")).join("");
}

const res = await client.messages.create({
  model: "claude-opus-5", // big model: we're asking it to reason and write at once
  max_tokens: 1024,       // maximum tokens it may generate in the response
  // We turn off the model's own reasoning so the step-by-step we see is
  // the one we asked for in the prompt, not its own
  thinking: { type: "disabled" },
  messages: [{ role: "user", content:
    `Ticket: "${incidencia}"\n` +
    // "Reason step by step" is, literally, the chain of thought
    `Reason step by step and finish with a JSON {categoria, respuesta}.` }],
});

// It all comes back in the same string: the reasoning and the JSON
const salida = texto(res);
That thinking line deserves an explanation, because it changes what the example means. Today’s reasoning models think on their own before answering, and that reasoning never reaches the text block: it travels separately and by default is not even shown. If we leave it on, the prompt’s “reason step by step” overlaps with something the model was already doing better. Turning it off makes the example teach manual chain of thought the way it was invented. In a real project, with a reasoning model, you would do the opposite: leave it on and lower the effort.
One call, one wait, and the model’s reasoning mixed in with the result. If the category comes out wrong, what you have is one whole bad string: there is nowhere to reach in.
With prompt chaining: two calls
The same task, split. The first call only classifies. Your code checks that the category is one of the ones you expect, and only then fires the second. That check between two steps is called a gate: a door the output has to pass through before the chain moves on.
// The closed list of valid categories: this is what we validate against
const CATEGORIAS = ["billing", "access", "bug", "other"];

// Step 1: classify only. Returns one word and nothing else.
const paso1 = await client.messages.create({
  model: "claude-haiku-4-5-20251001", // small model: this step is easy, so it's faster and cheaper
  max_tokens: 64,                     // one word is plenty
  messages: [{ role: "user", content:
    `Classify in a single word (${CATEGORIAS.join("|")}): "${incidencia}"` }],
});

// Step 1's output is already a variable of yours, not something inside the model
const categoria = texto(paso1).trim().toLowerCase();

// The gate: an ordinary if. If the word isn't in the list, we don't go on.
if (!CATEGORIAS.includes(categoria)) throw new Error(`Invalid category: ${categoria}`);

// Step 2: write the reply, now knowing what kind of ticket this is
const paso2 = await client.messages.create({
  model: "claude-opus-5", // here the big one: writing well is the hard job
  max_tokens: 512,
  messages: [{ role: "user", content:
    `Reply to this "${categoria}" ticket: "${incidencia}"` }],
});
The practical difference is that if line. categoria is a variable in your program: you can log it, store it in a database, show it on a dashboard, retry only step 1 if you don’t like it, or cut the chain short before spending the second call. None of that exists in the previous version. The full step-by-step for building a real chain, with retries and error handling, is in the prompt chaining guide, and if you would rather see it already built on a framework there are examples with code.
When to use each one, and when to use both
The rule is short: use chain of thought when the problem is reasoning, and prompt chaining when the problem is reliability.
Chain of thought helps with a task the model can do in one go but gets wrong if it answers off the cuff: a calculation with several steps, or a decision that depends on several conditions at once. It adds no piece to your architecture, it is text in the prompt.
Prompt chaining helps when the task splits cleanly into subtasks and you need to see what happens in between. Anthropic frames it as a trade: you pay more latency in exchange for more accuracy, because each call has an easier job [2]. That trade is worth it when a silent error costs you dearly.
And they combine with no trick at all, because every step of a chain is an ordinary call: inside that step you can ask for step-by-step reasoning just like in any other prompt. Chain on the outside, reasoning on the inside. It is the setup you end up with as soon as the flow has more than two steps, and building it by hand, deciding where to split and what to validate, is what you practise in the Design Patterns for AI Agents course.
Common mistakes
Building a chain when the problem was reasoning
The model gets a task wrong that it can do in one go, and you answer by splitting it into four calls. You have added three waits and three places where context gets lost, to fix something a sentence in the prompt would have fixed. Before splitting anything, ask for the steps inside the call you are already making and see whether that is enough.
Asking for step-by-step reasoning and expecting to validate it from code
The mirror mistake. You ask the model to reason, then try to read those steps from your program to check the intermediate result. That text is part of the answer, not a data field: it changes shape whenever it feels like it. If you need to check an intermediate from code, that intermediate has to be the output of a call of its own.
Believing the reasoning you see is the real reasoning
When the model writes “first I checked X, then I deduced Y”, that is generated text like any other, not a record of what happened inside. It tends to correlate with a better answer, which is why it works, but do not treat it as a reliable execution trace.
Putting all the reasoning in the system prompt and forgetting the window
The longer the prompt and the more reasoning the model generates, the more context window you take up, which is the limited space that holds everything the model reads and writes in one call. In a chain this takes care of itself, because each step starts with only what it needs.
Where few-shot and meta prompting fit
These are the other two techniques that get mixed up with these two, and putting them on the same map of layers removes a lot of the noise.
Prompt chaining vs few-shot prompting
Few-shot prompting is putting worked examples inside the prompt so the model copies the pattern. Few-shot changes what the model sees inside one call; prompt chaining changes how many calls there are. That is why they do not compete: few-shot lives on the same layer as chain of thought, and in fact they combine, because the original paper taught the reasoning with examples that already had it written out [1].
Prompt chaining vs meta prompting
Meta prompting is asking the model to write or improve the prompt you are going to use afterwards. Meta prompting hands you the text of a prompt, before anything runs; prompt chaining decides how many prompts run and in what order, while the flow is running. The normal thing is to use meta prompting to sharpen the prompt of one particular step in your chain. If you want the whole set of techniques laid out in order, it is in the essential prompt engineering patterns.
A checklist for deciding
- Is my problem one of reasoning (the model gets confused) or of reliability (sometimes it works and sometimes it doesn’t)?
- Is it enough to ask for reasoning inside the call I am already making?
- Do I need to see the intermediate result from code, to check it, store it or display it?
- Can I afford the extra latency of several calls where there used to be one?
- Could I say at which point I split the task, and why exactly there?
If you come out of this deciding you need to chain, the implementation checklist (each step’s output format, the gates, and what to do when one fails) is in the prompt chaining guide.
Sources
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models — Wei et al., 2022 — the origin of the term chain of thought and of the use of examples with written-out reasoning.
- Building Effective AI Agents — Anthropic — the definition of prompt chaining as a sequence of calls where each one processes the previous one’s output, and the latency/accuracy trade.
- Prompting best practices — Claude Platform Docs — the recommendation of general instructions over prescriptive steps with thinking on, and manual chain of thought as the alternative when it is off.
Frequently Asked Questions
Is chain of thought still needed with reasoning models?
Less, and differently. With reasoning on, Claude’s documentation recommends general instructions like “think hard” rather than a hand-written step-by-step plan, because the model’s reasoning usually goes beyond what you would prescribe [3]. Manual chain of thought remains the alternative for when reasoning is off.
Can I use prompt chaining and chain of thought at the same time?
Yes, and it is the normal thing as soon as the flow grows. Each step of the chain is an independent call, so inside that step you can ask for reasoning just like in any standalone prompt. The chain organises the flow from the outside and the reasoning works inside each link. One nuance: however many steps you chain, you are still the one deciding the order in your code; when the model decides what to do next, you are talking about an agent.
Which one uses more tokens?
It depends on the task and there is no fixed rule. Chain of thought spends output tokens on the reasoning, which on a long task can be a lot. Prompt chaining spreads the work across shorter calls, but repeats instructions and context in each one. The honest way to know is to measure your own case with the usage counters the API itself returns.
Are few-shot and prompt chaining alternatives?
No, and choosing between them makes no sense. Few-shot prompting improves one call by putting worked examples in it; prompt chaining decides how many calls there are. You can put few-shot examples inside step 1 of your chain and none in step 2, because they are decisions on different layers.
Related articles
Prompt Chaining: How to Break Down Complex Tasks Into Simple Steps
Learn how to divide difficult tasks into sequential LLM calls. With line-by-line commented TypeScript code and no external frameworks.
Prompt Engineering for Developers: 5 Patterns With Code
The 5 prompt engineering patterns: zero-shot, few-shot, CoT, role prompting, and structured output with real TypeScript code.
Prompt Chaining with LangChain: Copy-Paste Examples
Prompt chaining examples with LangChain in TypeScript, ready to copy, plus the same chain without a framework so you can compare. Full working code.